文本的数据分析进阶

政务大数据应用与分析 (80700673)

胡悦

清华大学社会科学学院

个人简介

个人经历

  • 政治学博士(University of Iowa)
    • 信息学(Graduated Certificate in Informatics)
  • 清华大学计算社会科学平台(副主任)
    • 清华数据与治理中心(副主任)
    • 计算社会科学编程语言证书项目(负责人)
    • Learning R with Dr. Hu & Friends 工作坊(创始人)

研究兴趣:认知、行为与现代性

  • 方法路径:计算政治学
    • 实验室和调查实验
    • 潜变量分析、网络分析、空间分析
    • 文本大数据分析、数据可视化

研究领域:比较政治、国家治理

  • W. 心理学
    • 政治认知治理
    • 行为公共政策
    • 政治传播
  • W. 经济学
    • 经济不平等感知
    • 公共设施、服务均等化
  • W. 语言学
    • 权力背书的语言效果与机制
    • 语言政策的治理功能

复习

King (2015): [The big-data approach is] the end of the quantitative-qualitative divide.

你应该已经知道……

  • 你能用文本数据做什么
    • 你分析的是文字还是语言?
    • Close reading or distant reading?
    • 文本/音频/视频分析的理论基础是什么?
  • 如何获取数据
    • 文本数据的获取渠道有哪些?
    • 网络爬取与正则表达式
  • 如何处理数据
    • 如何结构化文本数据?
    • 文本预处理的步骤有哪些
    • Tokenization的两种含义是什么?
  • 如何分析数据
    • 词频能分析出什么?
    • 如何鉴别关键词?
    • 词的相似度?
    • 主题模型在干什么?
      • Bag of Words (BOW)?

提要

学完本课,你将了解:

  • 如何捕捉“草蛇灰线”:词汇层级信息汇入
  • 如何提升主题模型质量:概念层级信息汇入
  • 词嵌入和LLM干了什么:语义层级信息汇入

本讲的核心议题:突破词基限制,纳入有用信息

Warning

  • 学习本课内容,你不需要编程知识😱
  • 应用本课内容,你需要一种编程知识😜

问题源头

让计算机读懂人言的代价

Document-Term Matrix (DTM)

Document-Term Matrix (DTM)

丢失了什么

  • 词的重要性
  • 语序/位置
  • 虚词
  • 语法
  • Meta data

词汇层级信息汇入

加权

DTM的问题:

  1. 未将词的重要性纳入考量
  2. 过度体现常见词
  3. 轻视少见词

举例:Term frequency-inverse document frequency (TF-IDF)

\[\displaystyle \mathrm {tf} (t,d)={\frac {f_{t,d}}{\sum _{t'\in d}{f_{t',d}}}},\] where \(f_{t,d}\) is the number of times that term t occurs in document d. 

\[\displaystyle \mathrm {idf} (t,D)=\log {\frac {N}{|\{d:d\in D{\text{ and }}t\in d\}|}},\]

  • \(N\): total number of documents; D.
  • \(|\{d\in D:t\in d\}|\) : number of documents where the term \(t\) appears.

加权带来什么

  • 好处:
    1. 识别重要词汇
    2. 减少常见词汇的权重
    3. 提高机器学习性能 (why?)
  • 副作用:
    1. 假定词汇独立(与DTM相同)
    2. 对在语料库中非常罕见但在特定文档中出现过几次的罕见词汇给予高权重
    3. 对语料库的大小和多样性敏感

N-gram分析

  • Markov Model of Order N
    • Unigram: 清华 大学 社会 科学 学院
    • Bigram: 清华大学 大学社会 社会科学 科学 学院
    • Trigram:清华大学社会 大学社会科学 社会科学学院

搭配分析

  • 连续搭配(Contiguous collocations):在文本中直接相邻出现。
  • 揭示语言使用中的模式,这些模式从查看单个单词时并不立即明显。

示例数据:2012年到2016年的6,000篇《卫报》新闻文章

Corpus consisting of 6,000 documents and 9 docvars.
text136751 :
"London masterclass on climate change | Do you want to unders..."

text118588 :
"As colourful fish were swimming past him off the Greek coast..."

text45146 :
"FTSE 100 | -101.35 | 6708.35 | FTSE All Share | -58.11 | 360..."

text93623 :
"Australia's education minister, Christopher Pyne, has vowed ..."

text136585 :
"block-time published-time 3.05pm GMT | The former leader of ..."

text65682 :
"Darren Wilson will be unable to return to work as a police o..."

[ reached max_ndoc ... 5,994 more documents ]

Collocation 示例

  • 最常见的词对(pairs of words)
  • 最常见的三词模式(three-word patterns)
       collocation count count_nested length    lambda         z
1    david cameron   861            0      2  8.186347 147.76683
2     donald trump   774            0      2  8.353969 123.09383
3   george osborne   364            0      2  8.687785 107.95642
4  hillary clinton   526            0      2  9.125811 102.77388
5         new york  1016            0      2 10.474860 100.52567
6    islamic state   330            0      2  9.829185  98.41582
7      white house   478            0      2  9.938355  96.56095
8   european union   351            0      2  8.288569  95.07175
9    jeremy corbyn   244            0      2  8.756533  91.07510
10   boris johnson   245            0      2  9.691163  85.00475
                  collocation count count_nested length     lambda          z
1             new south wales    85            0      3  8.9133533  4.3907828
2       european central bank    95            0      3  4.4049316  4.3095051
3 international monetary fund   101            0      3  2.2155907  1.0661709
4               new york city    96            0      3  1.0061265  0.6134988
5      photograph mike bowers    90            0      3  0.5209553  0.3473888
6              new york times   128            0      3 -0.5342360 -0.3516073

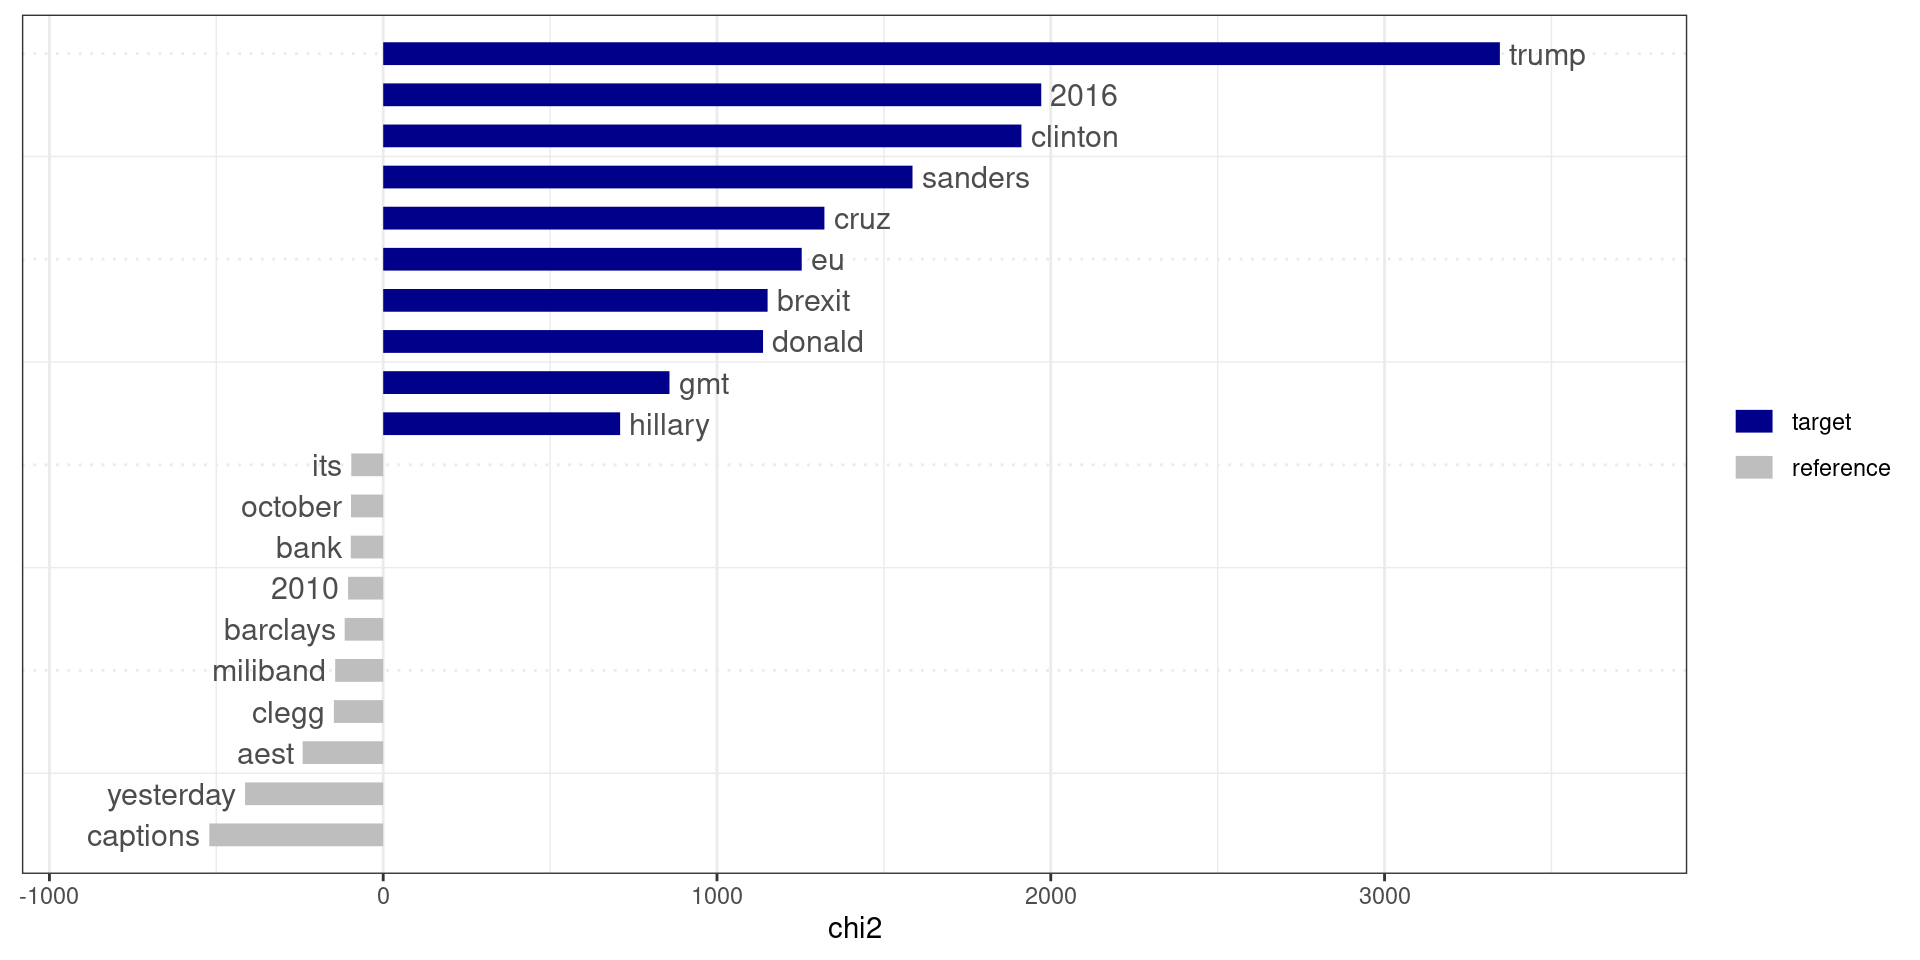
“靶向”分析

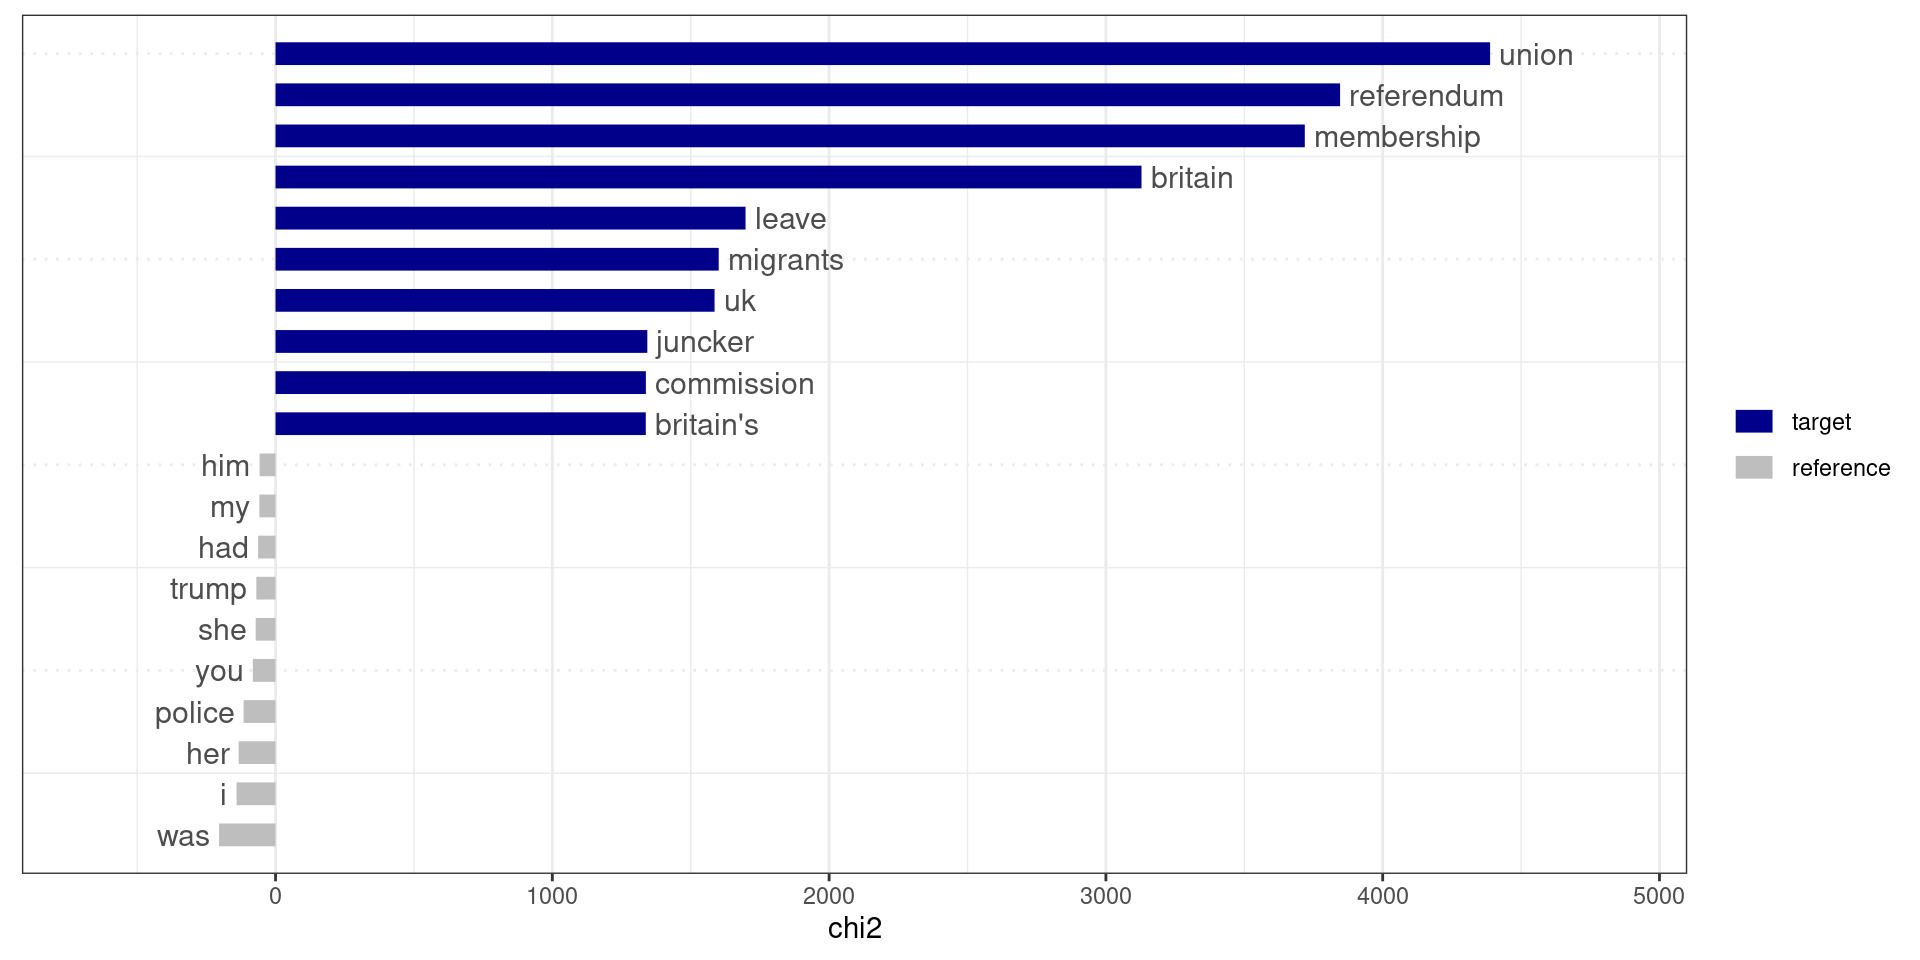
  • 关键性(Keyness):识别在目标语料库中比在参照语料库中统计上更频繁出现的词语的度量方法 (Gabrielatos 2018)

示例1:对比《卫报》新闻2016年与2012—2015年之间的新闻

Keyness 示例2

在2012年到2016年的6,000篇《卫报》新闻文章中与欧盟(“EU”, “europ*“,”european union”)相关的词汇
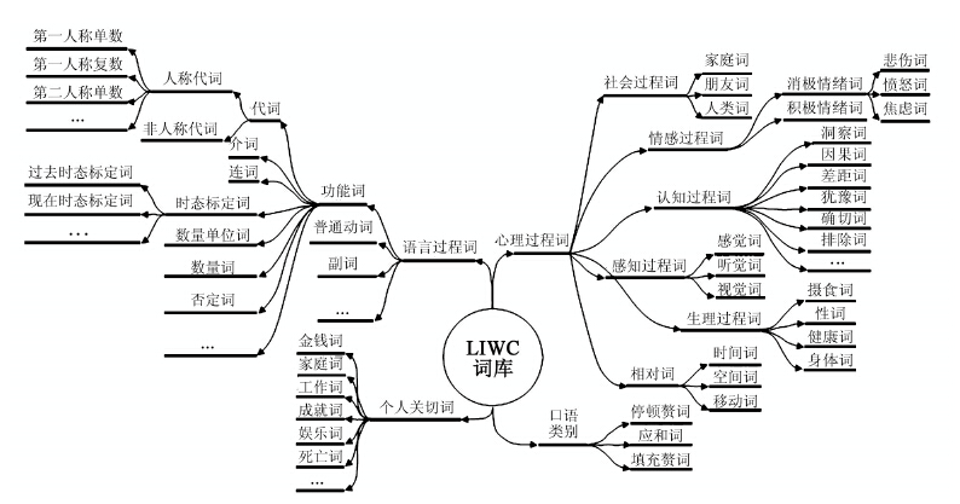
“入木三分”分析 (Liu 2022)

小结

  • Weighing ← 从词频攫取信息
  • N-gram ← 从邻居攫取信息
  • Collocation ← 从共现攫取信息
  • Keyness ← 从关键词定位攫取信息
  • Functional words ← 从社会心理攫取信息

概念层级信息汇入

主题模型能干什么

主题模型缺什么

“他的脸突然被魔杖的光照亮了。这是一张因痛苦、恐惧和愤怒而变得生动的脸。红色的眼睛向那个看不见的男孩站着的地方射去,他的隐形斗篷遮住了他。他的声音,当他发出声音时,就像一个冬天的夜晚一样冷。他说,“我回来了,比以前更强大了。”

  • 主题之间的联系
  • 篇章之间的联系
  • 内容背景知识(外部信息)


STM/SeedLDA/keyATM

Correlated Topic Model (CTM)

主题之间彼此关联被纳入考量

LDA

LDA

CTM

CTM

\[\{\mu,\Sigma\}\sim N(\mu,\Sigma).\]

Sparse Additive Generative Model (SAGE)

每个主题都被赋予一个模型,能够描述给予恒定背景分布对数频率的偏差。

SAGE

SAGE

Structure Topic Model (STM, Roberts et al. 2013)

CTM + SAGE

STM

STM

操作

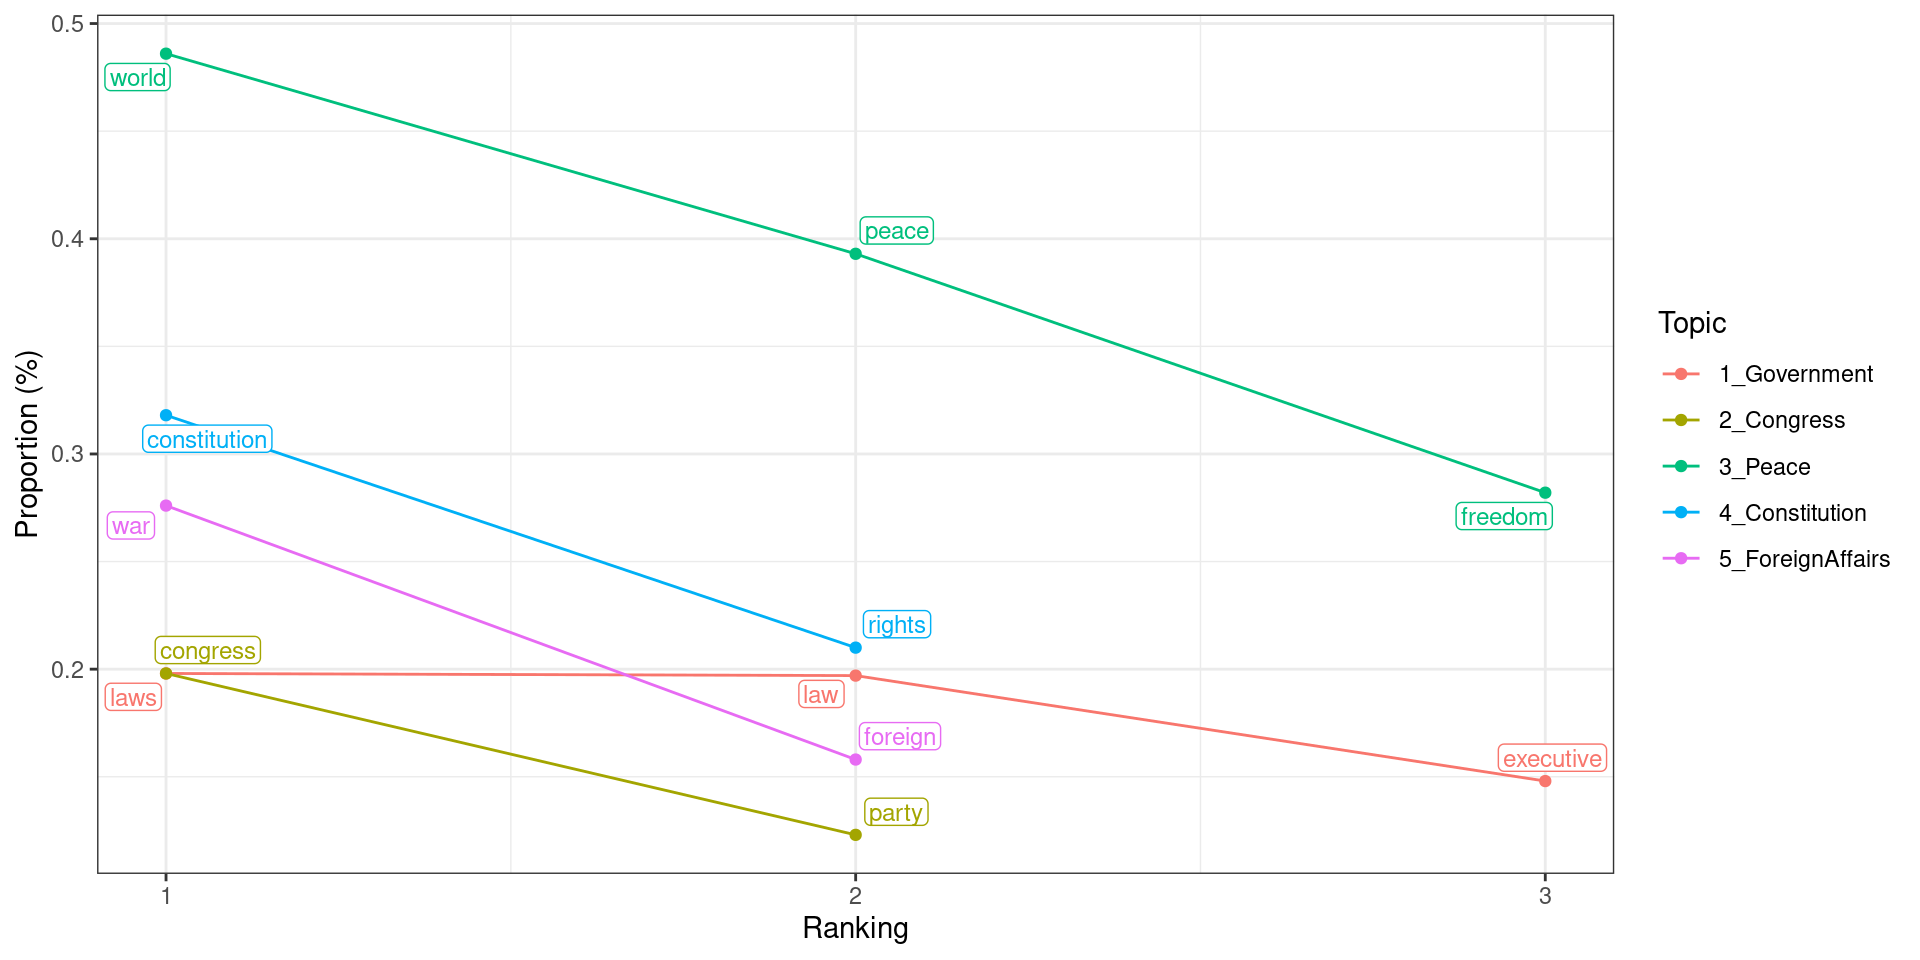
示例:美国总统就职演说数据

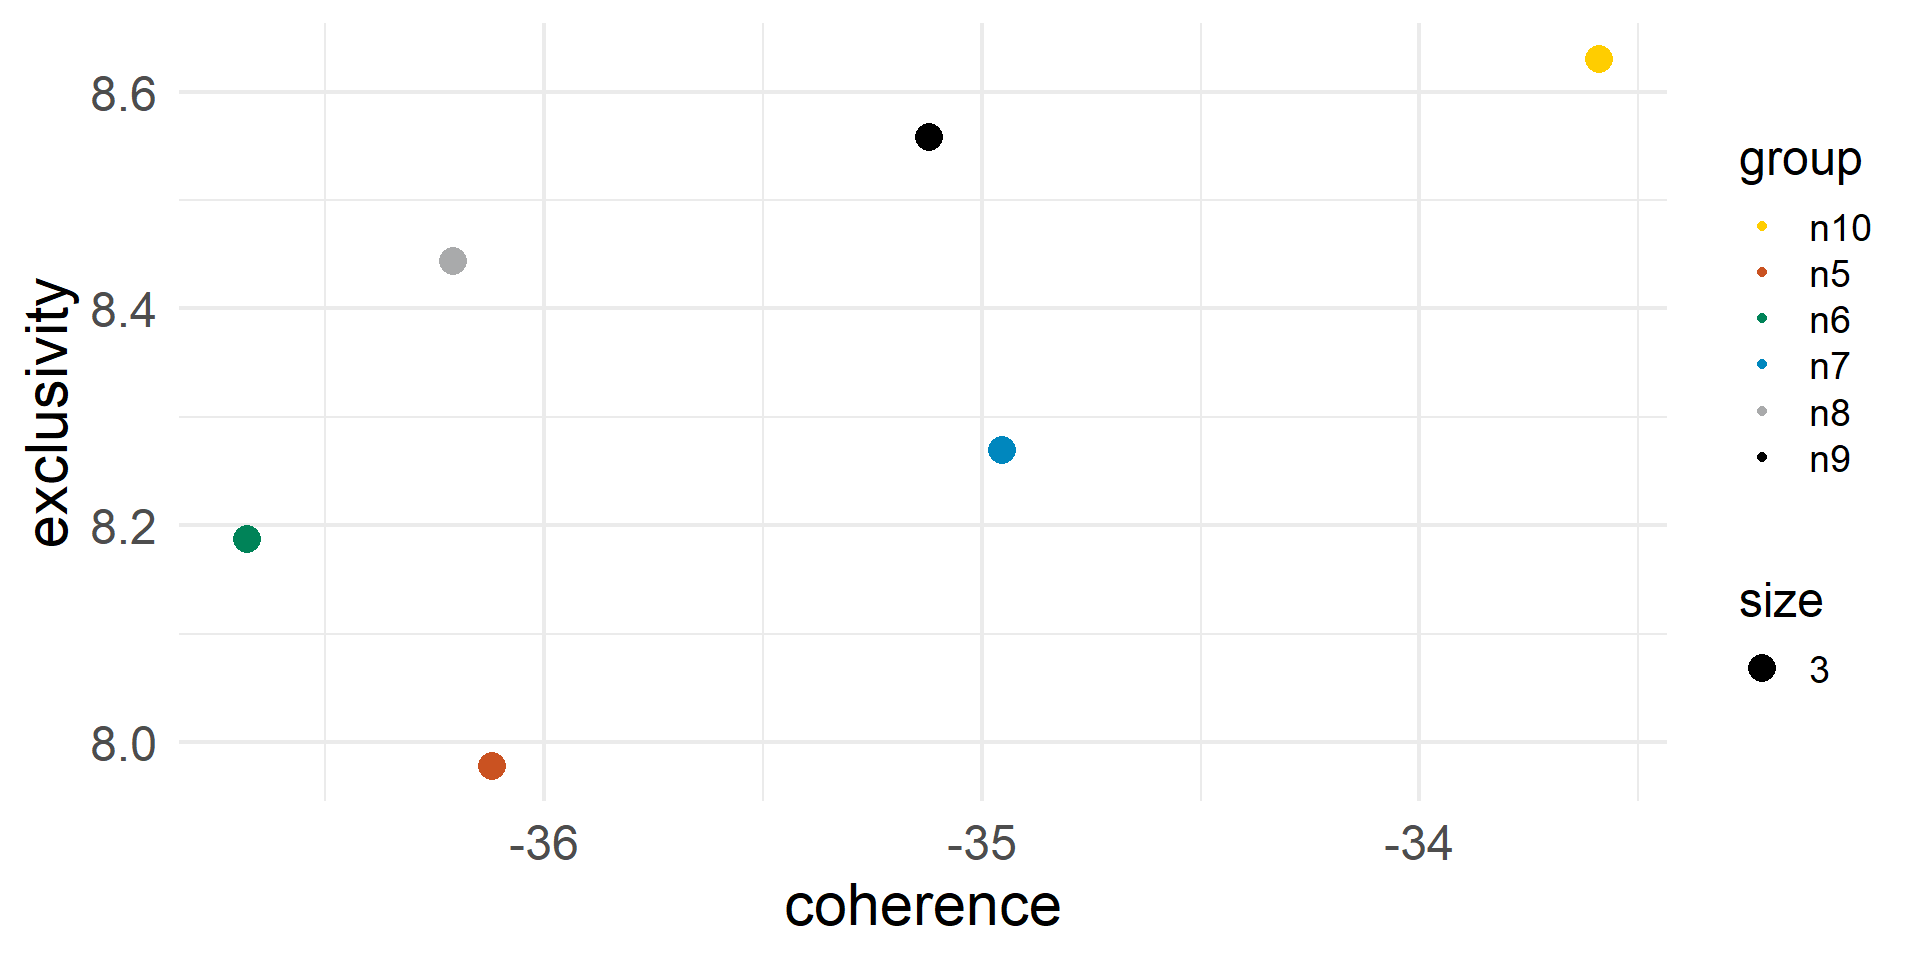
  1. 设定主题数目

2. 主题归类

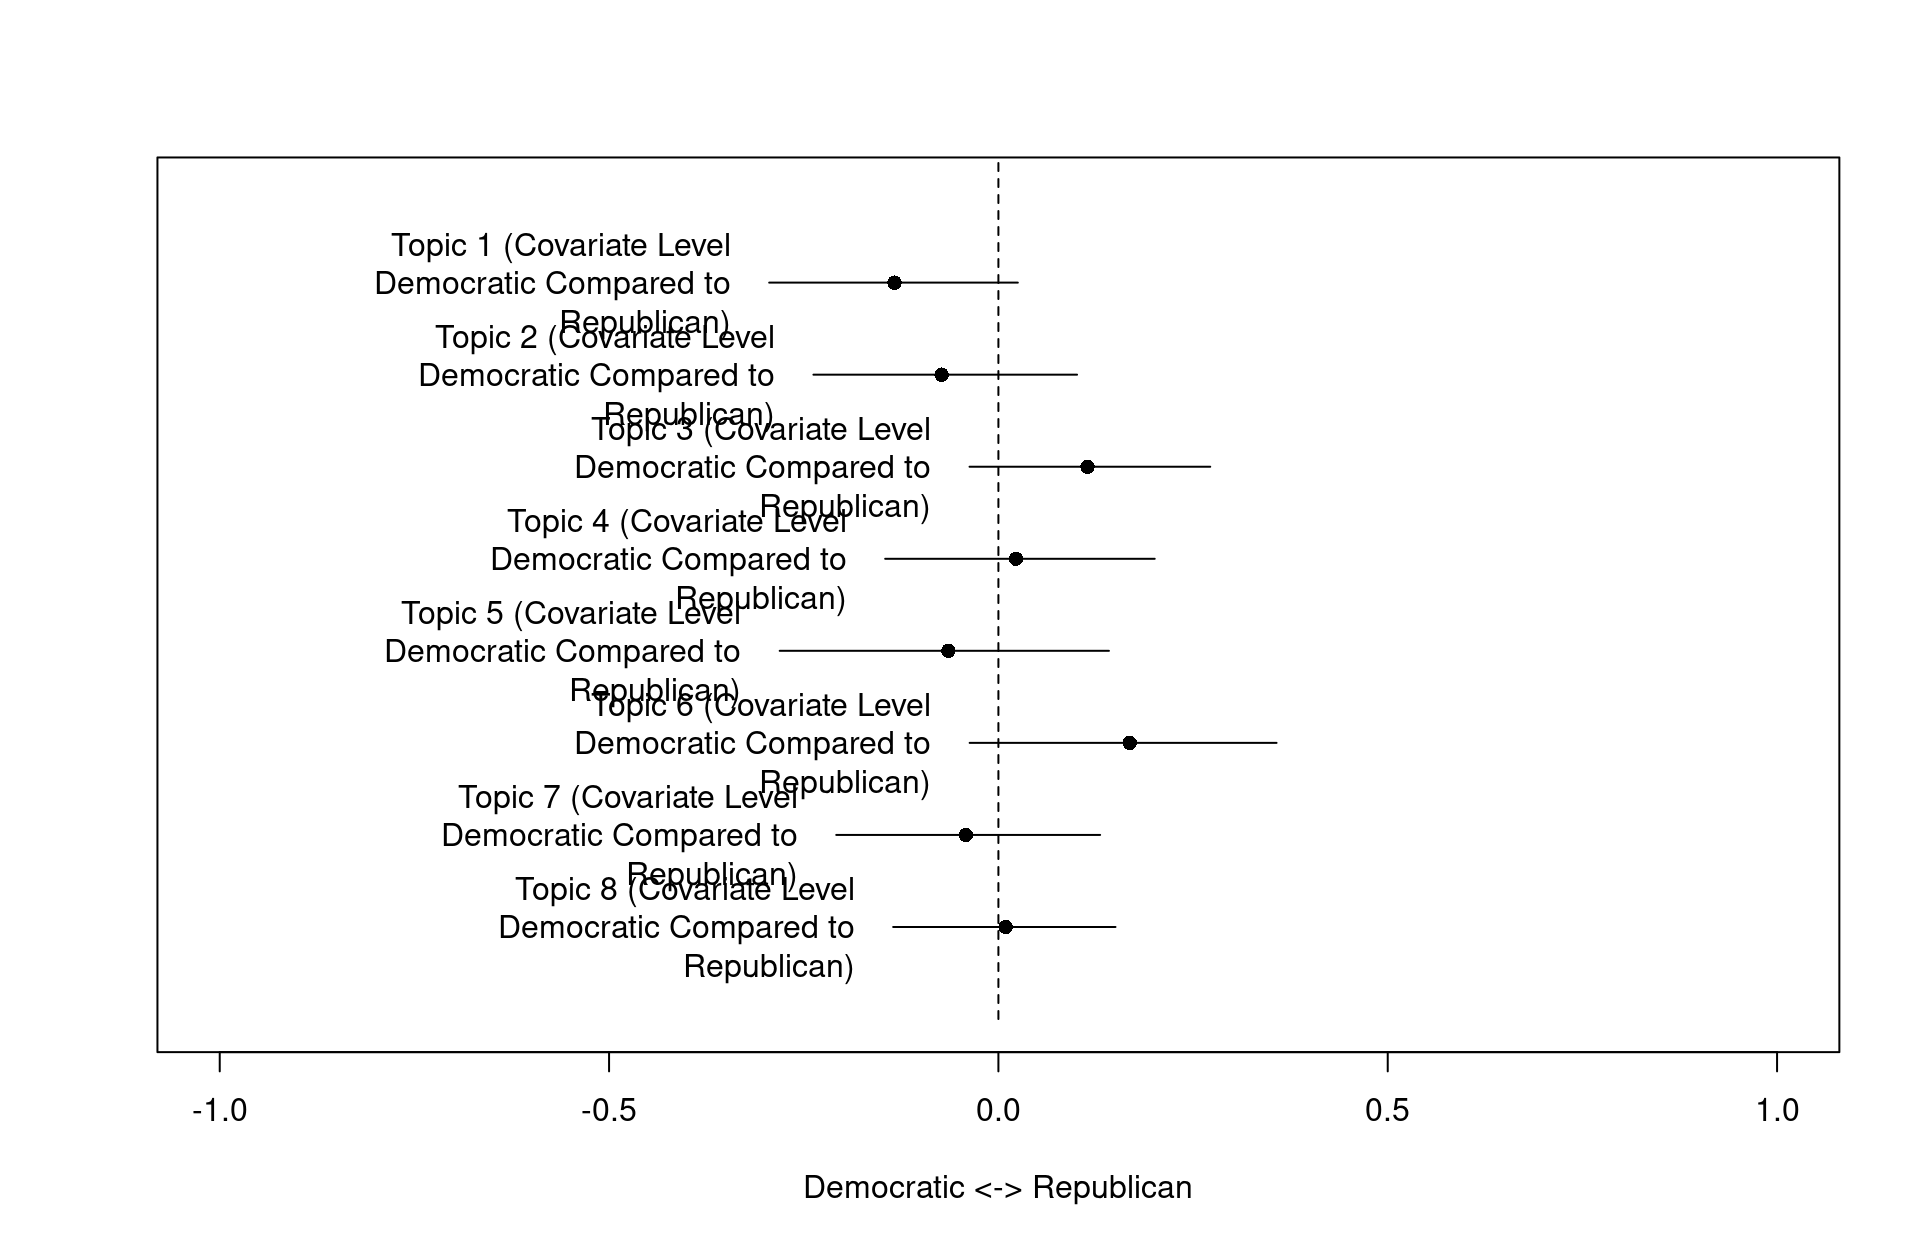
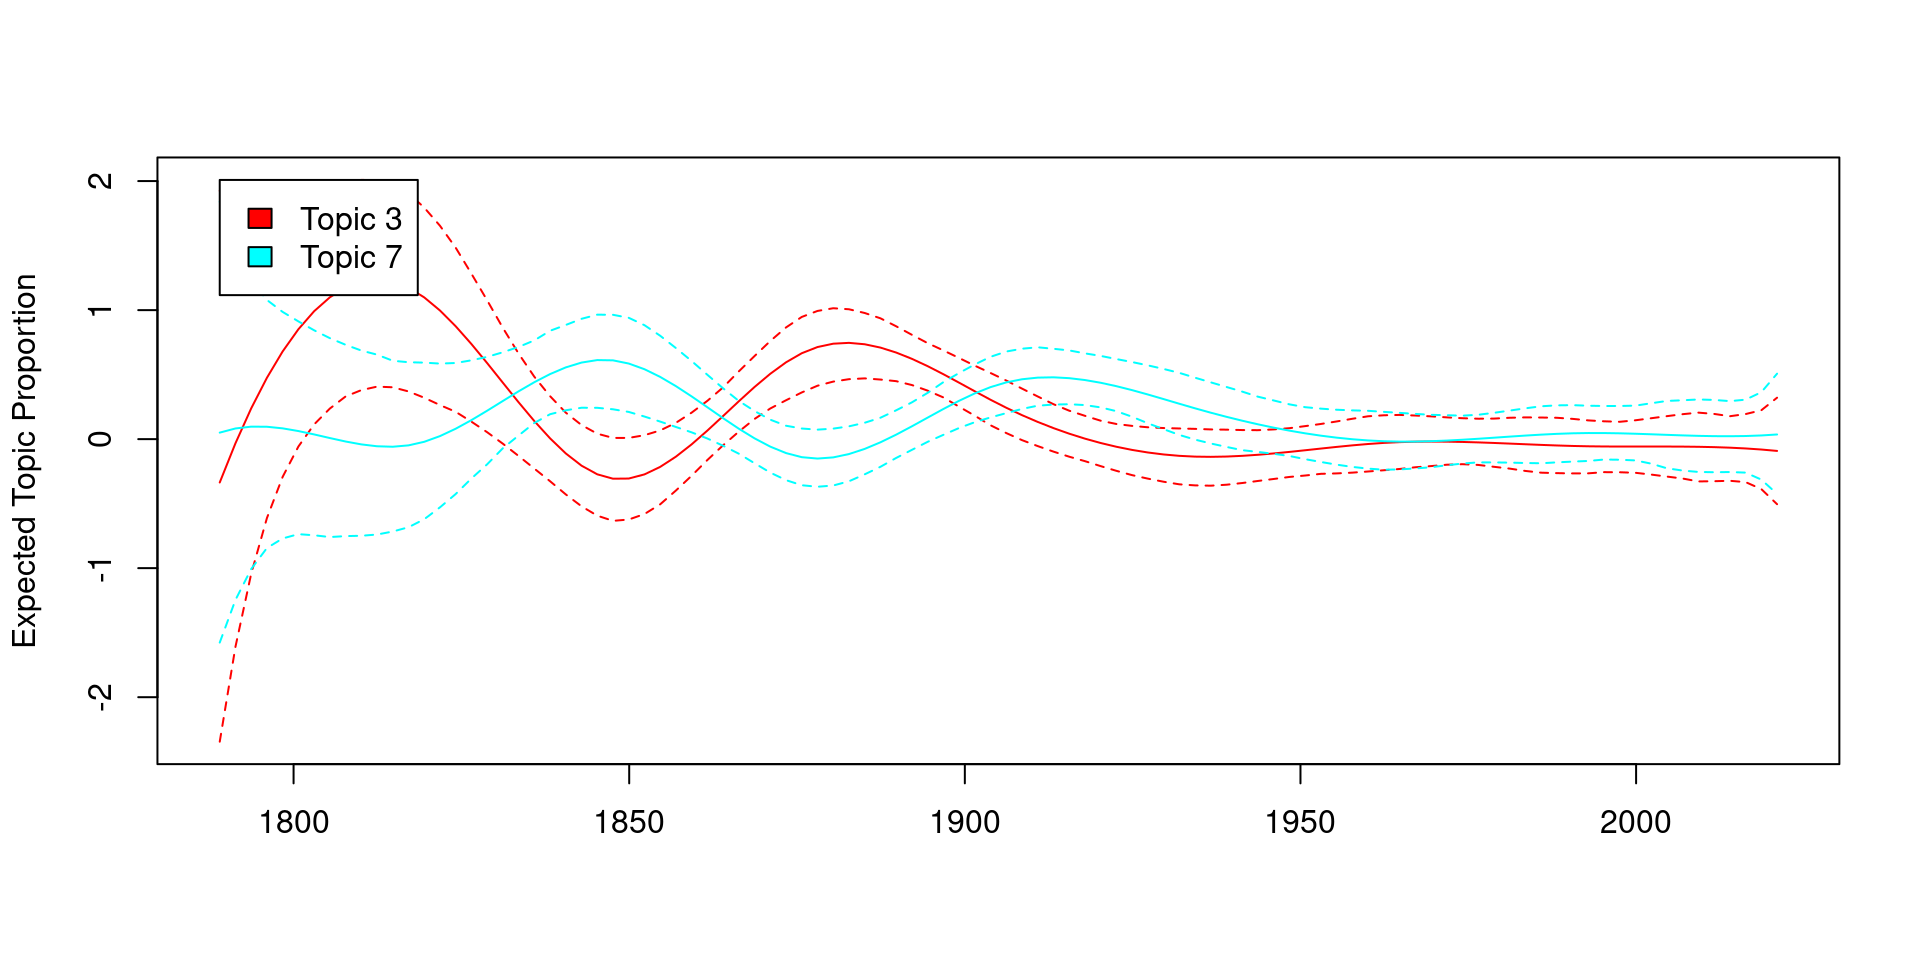
\[Topic \sim Party + s(Year).\]

Topic 1 Top Words:
     Highest Prob: ,, ., us, world, america 
     FREX: story, thank, americans, :, moment 
     Lift: —, 1980, 30, 50th, adventure 
     Score: story, americans, thank, –, senator 
Topic 2 Top Words:
     Highest Prob: ,, ., ;, government, people 
     FREX: case, parties, measures, former, circumstances 
     Lift: 120,000,000, 14th, 1774, 1778, 1801 
     Score: fellow-citizens, case, revenue, roman, academies 
Topic 3 Top Words:
     Highest Prob: ,, ., people, government, upon 
     FREX: partisan, ballot, citizenship, patriotic, commercial 
     Lift: 1780, 1790, 1880, 1886, 1890 
     Score: revenue, ballot, arrive, policy, patriotic 
  • Highest Prob:高频词
  • FREX:主题高频词
  • lift:通过词语在其他主题中的频率相除来加权词语
  • score:将词语在主题中的对数频率除以词语在其他主题中的对数频率

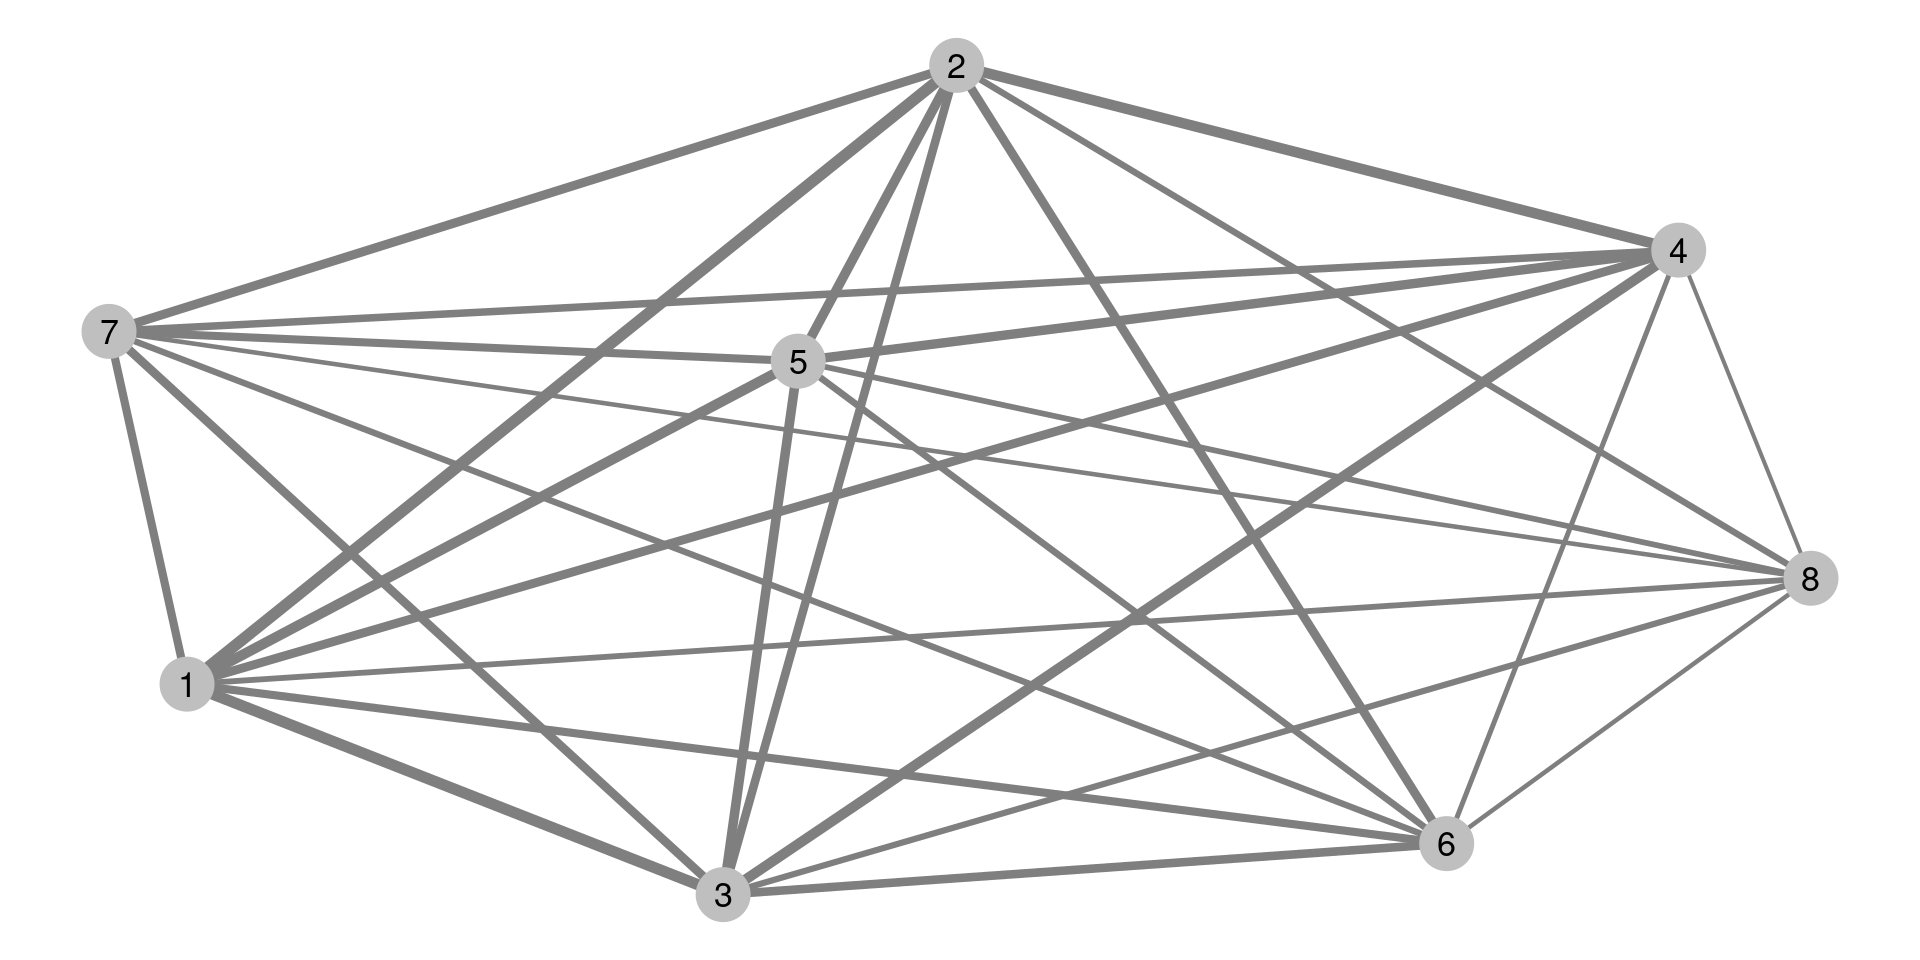
3. 主题相关性

以余弦相似度来计算相关性,越接近于1表示两个主题越相关,越接近于0表示两个主题越不相关。
协变量的影响:党派
协变量的影响:时间
Seed LDA

以种子词(seeds)引领主题分类。

示例数据:《卫报》2016

种子词:经济、政治、社会、外交和军事,基于对该类新闻的认知获取

Dictionary object with 5 key entries.
- [economy]:
  - market*, money, bank*, stock*, bond*, industry, company, shop*
- [politics]:
  - lawmaker*, politician*, election*, voter*
- [society]:
  - police, prison*, school*, hospital*
- [diplomacy]:
  - ambassador*, diplomat*, embassy, treaty
- [military]:
  - military, soldier*, terrorist*, marine, navy, army

效果比较:LDA

topic1 topic2 topic3 topic4 topic5
labor refugees violence clinton oil
corbyn syria officers sanders markets
australian brussels prison cruz climate
budget isis victims obama energy
johnson talks hospital hillary sales
turnbull un sexual trump's food
australia syrian cases bernie prices
leadership military child ted rates

效果比较:Seed LDA

economy politics society diplomacy military
markets clinton hospital corbyn military
banks sanders schools labor syria
oil cruz prison turnbull officers
sales obama water johnson refugees
energy hillary food budget terrorist
prices trump's hospitals cabinet isis
stock bernie climate brussels army
sector senator violence talks syrian

Keyword-Assisted Topic Models (keyATM, Eshima, Imai, and Sasaki 2023)

  • 针对概念测量而设计,而非探索主题
  • 基于关键词(种子词) (类似于seedLDA)
  • 允许没有关键词的主题 (不同于seedLDA)
  • 对词频加权防止“词频主导”现象(类似于 weightedLDA)
  • 允许文档向量、元信息的动态变化 (类似于STM)
  • 贝叶斯方法
  • 当种子词质量高时,性能优于加权LDA和STM

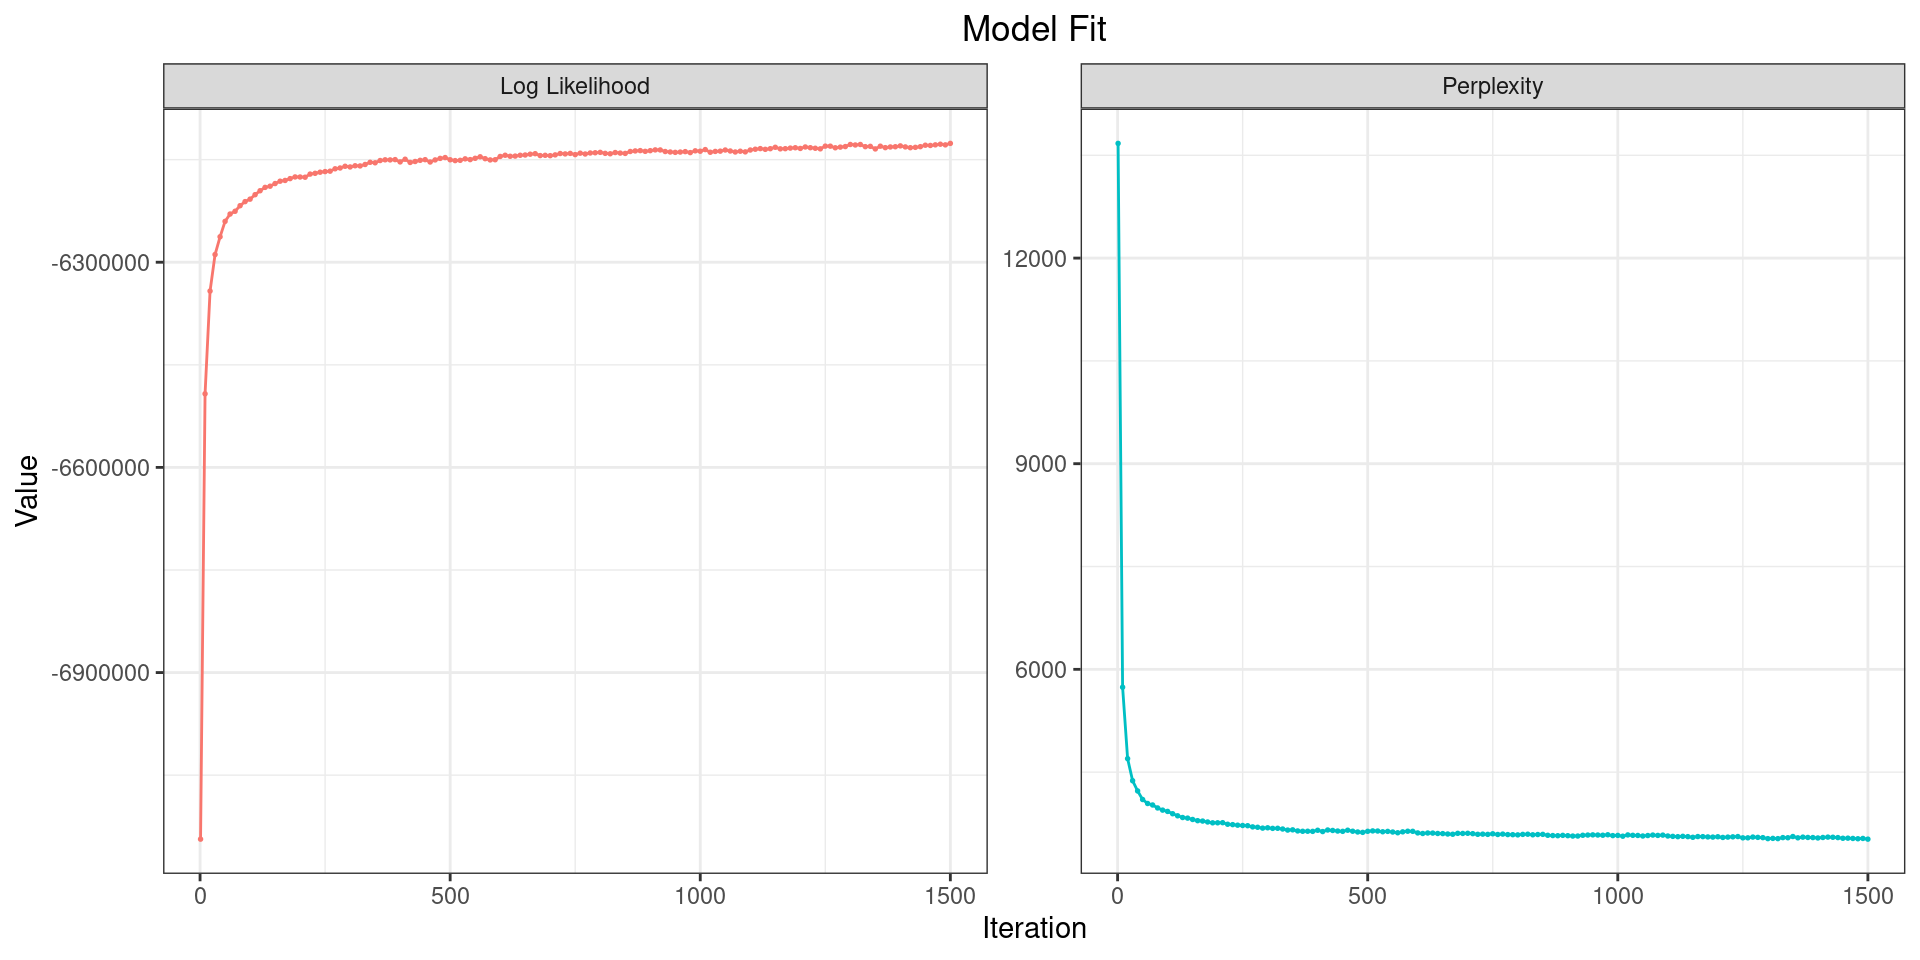
Model Fit

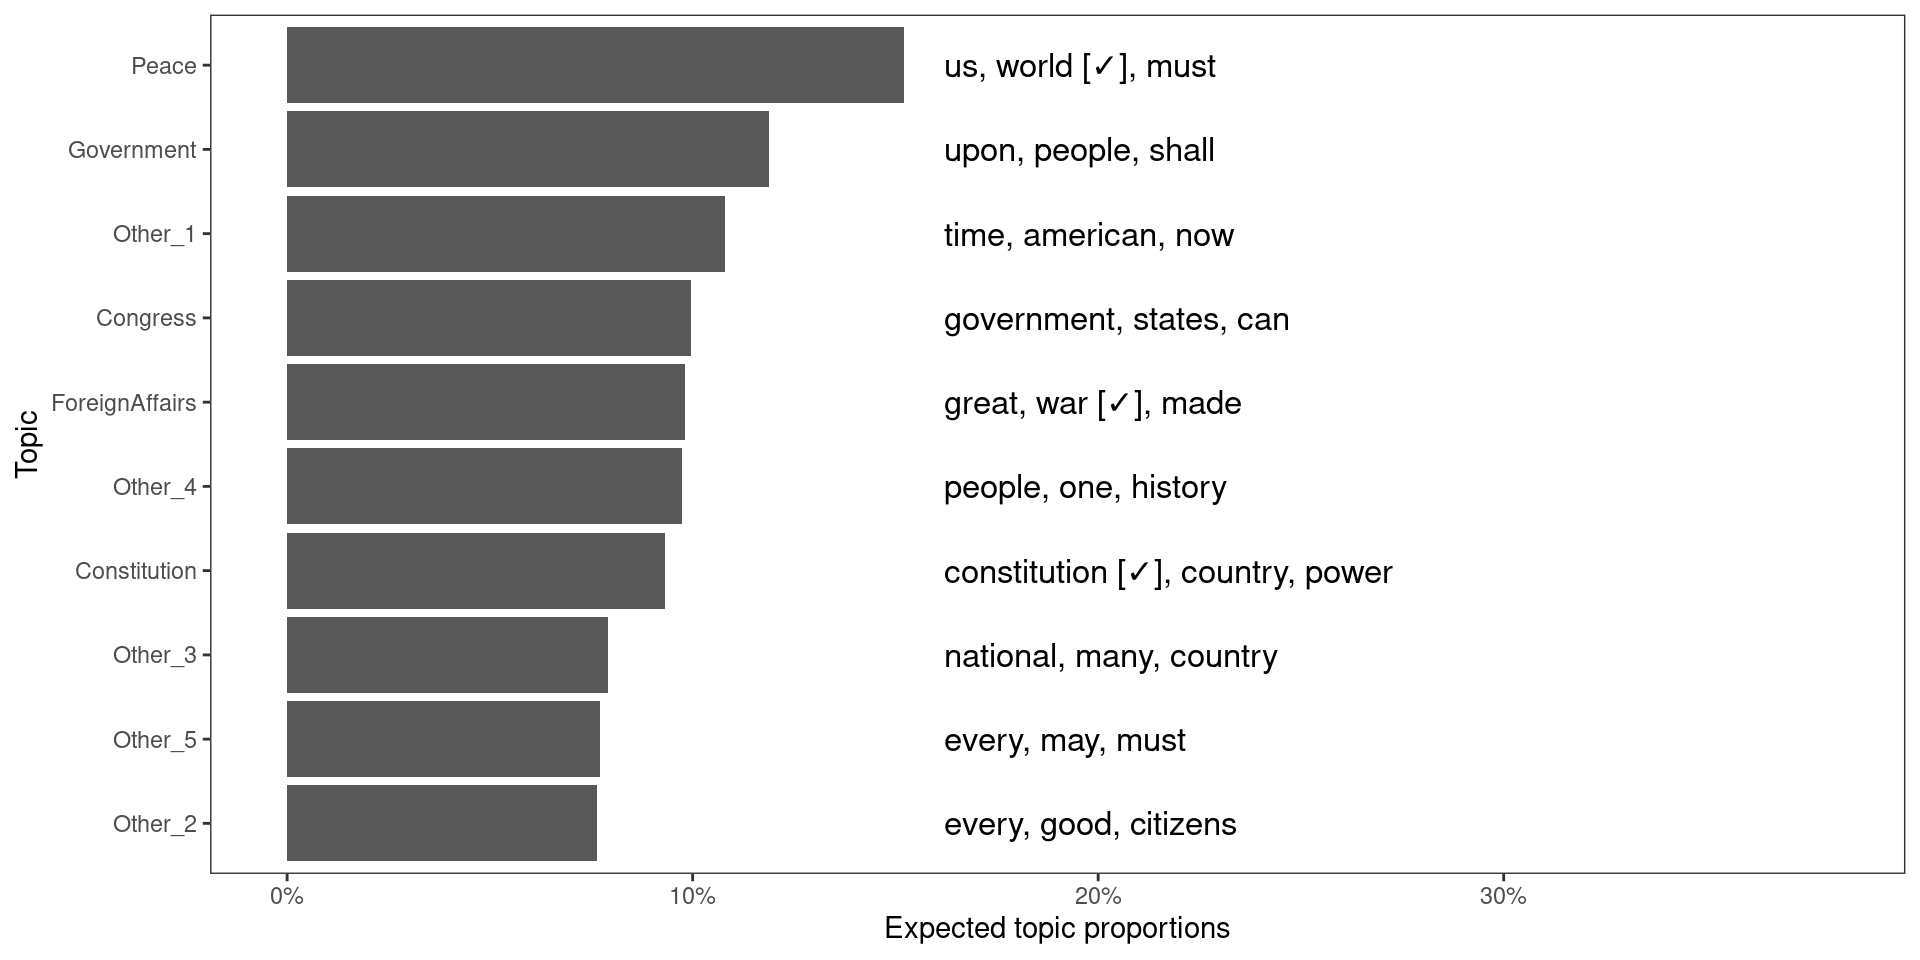
Base Model Result
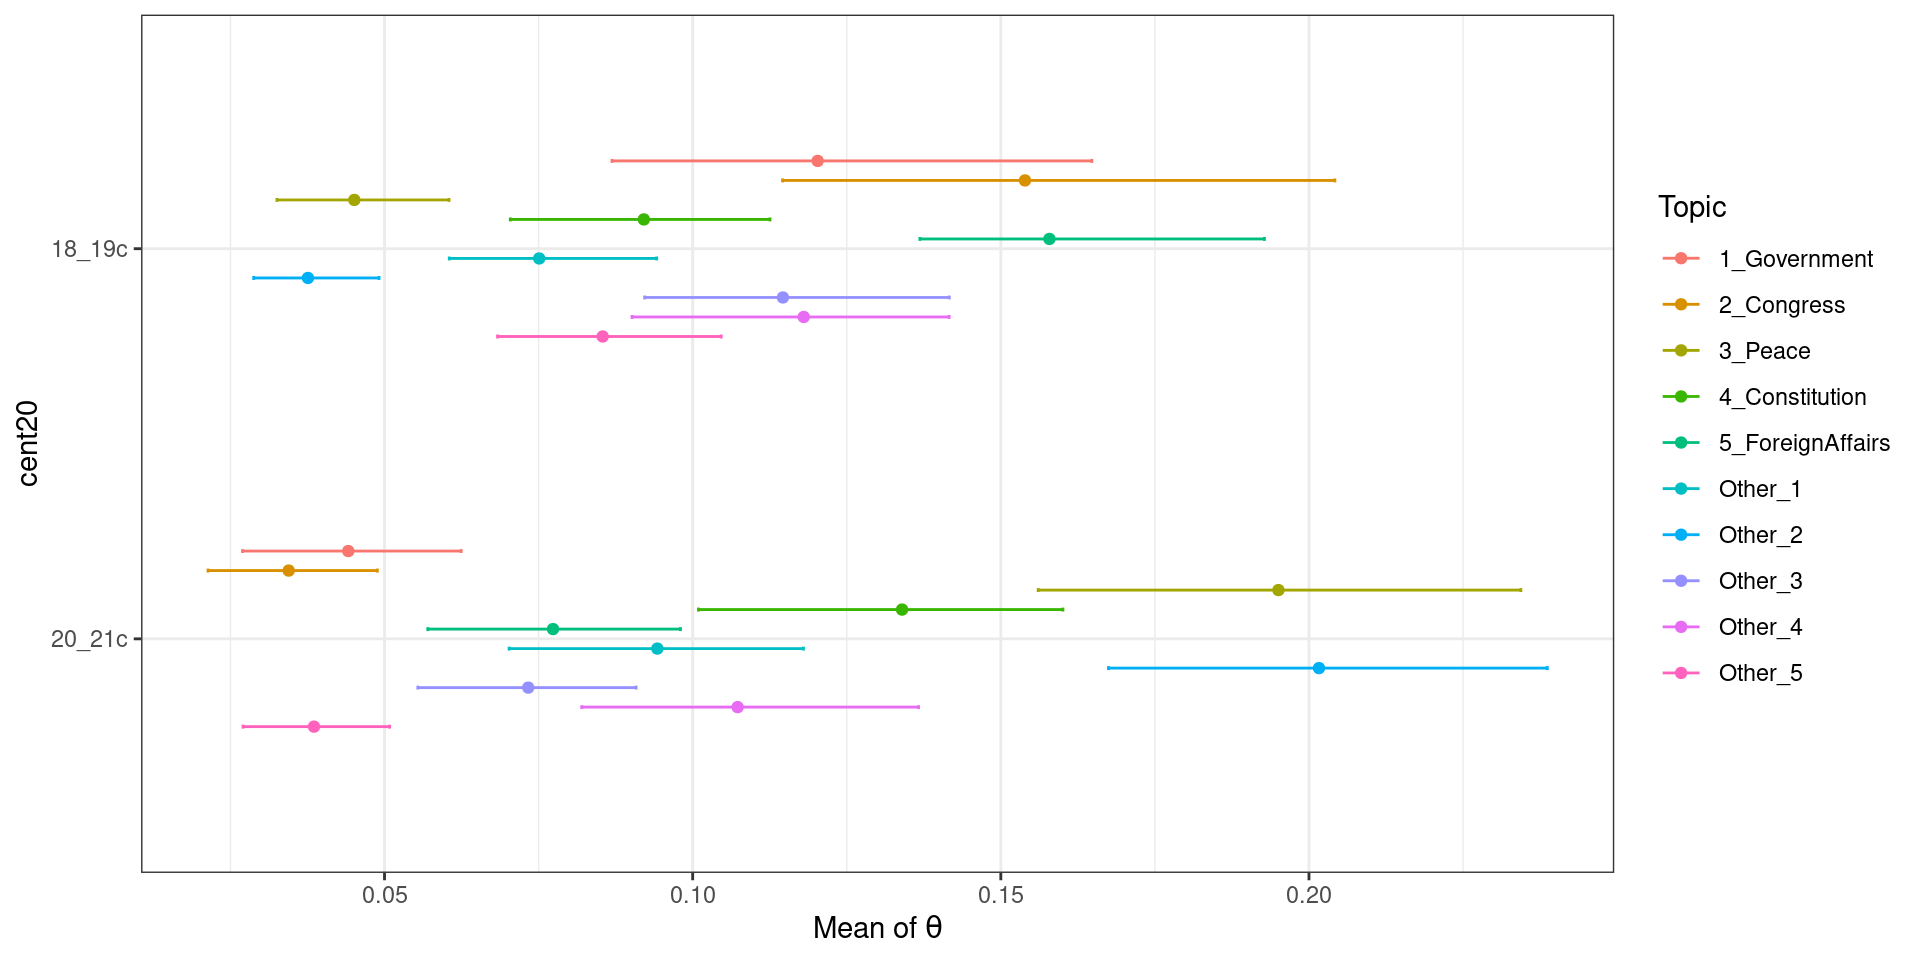
Covariate Effect
Topic Dynamics
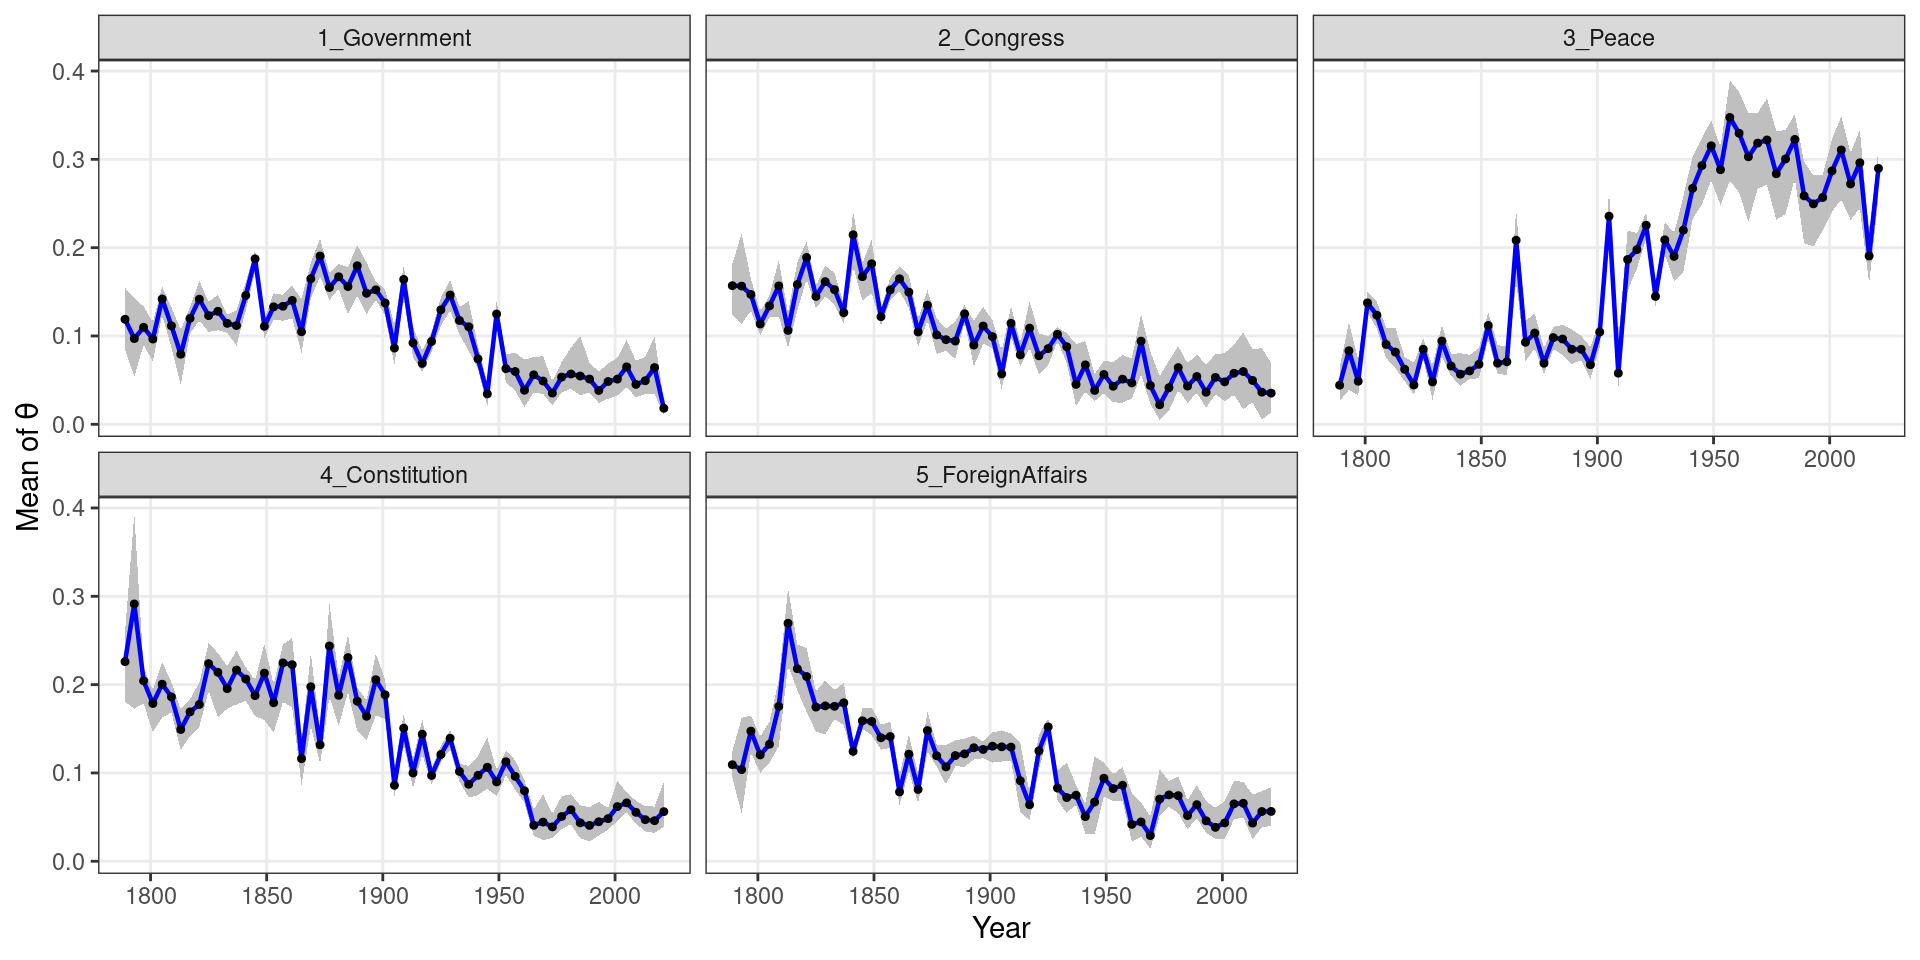
小结

  • Weighing ← 从词频攫取信息
  • N-gram ← 从邻居攫取信息
  • Collocation ← 从共现攫取信息
  • Keyness ← 从关键词定位攫取信息
  • Functional words ← 从社会心理攫取信息
  • STM ← 纳入概念关系外部信息
  • SeedLDA ← 纳入背景知识
  • keyATM ← 纳入研究意图

语义层级信息汇入

给词义建模:词嵌入(Word embedding)

Words’ meanings depend not just on immediate neighbors

能做什么

  • 纳入词语意义的表达
    • 哪个最接近paris - france + germany(柏林)?
    • 哪个最接近berlin - germany + uk + england(伦敦)?
  • 与分类和聚类相比: Document-feature matrix → context-feature matrix (FCM)
    • 分类:不关注单个词语间的关系,而是关注词语在文档中的分布。
    • 聚类:提供对文档集合内容的更高级,而不是专注于单个词语的含义。
  • 应用
    • 词条表征(term representation)
    • 情感分析(sentiment analysis)

应用举例:Latent Semantic Scaling (Watanabe 2021)

  • 专门用于区分对立的立场
  • 基于词嵌入技术的,在构建模型之前将文档和特征转换为高维度向量空间
    • GloVe
    • Singular Value Decomposition (SVD)

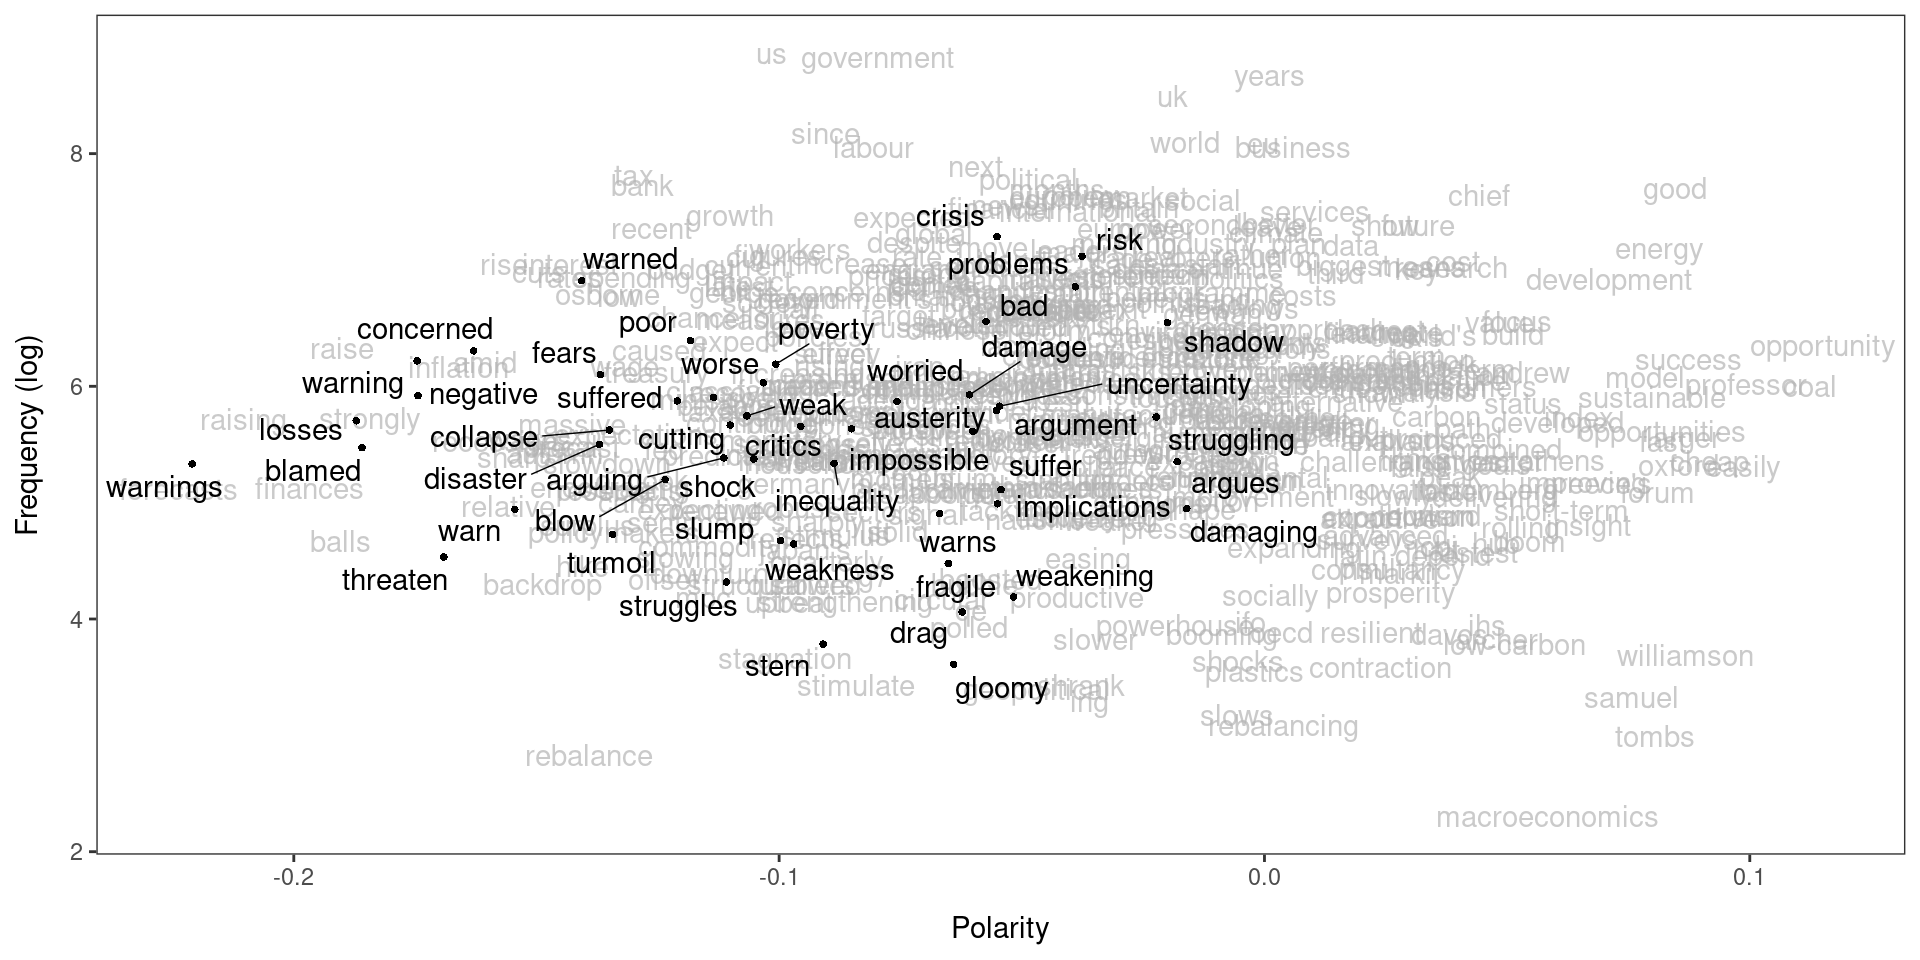
应用:判断《卫报》新闻的情感走向
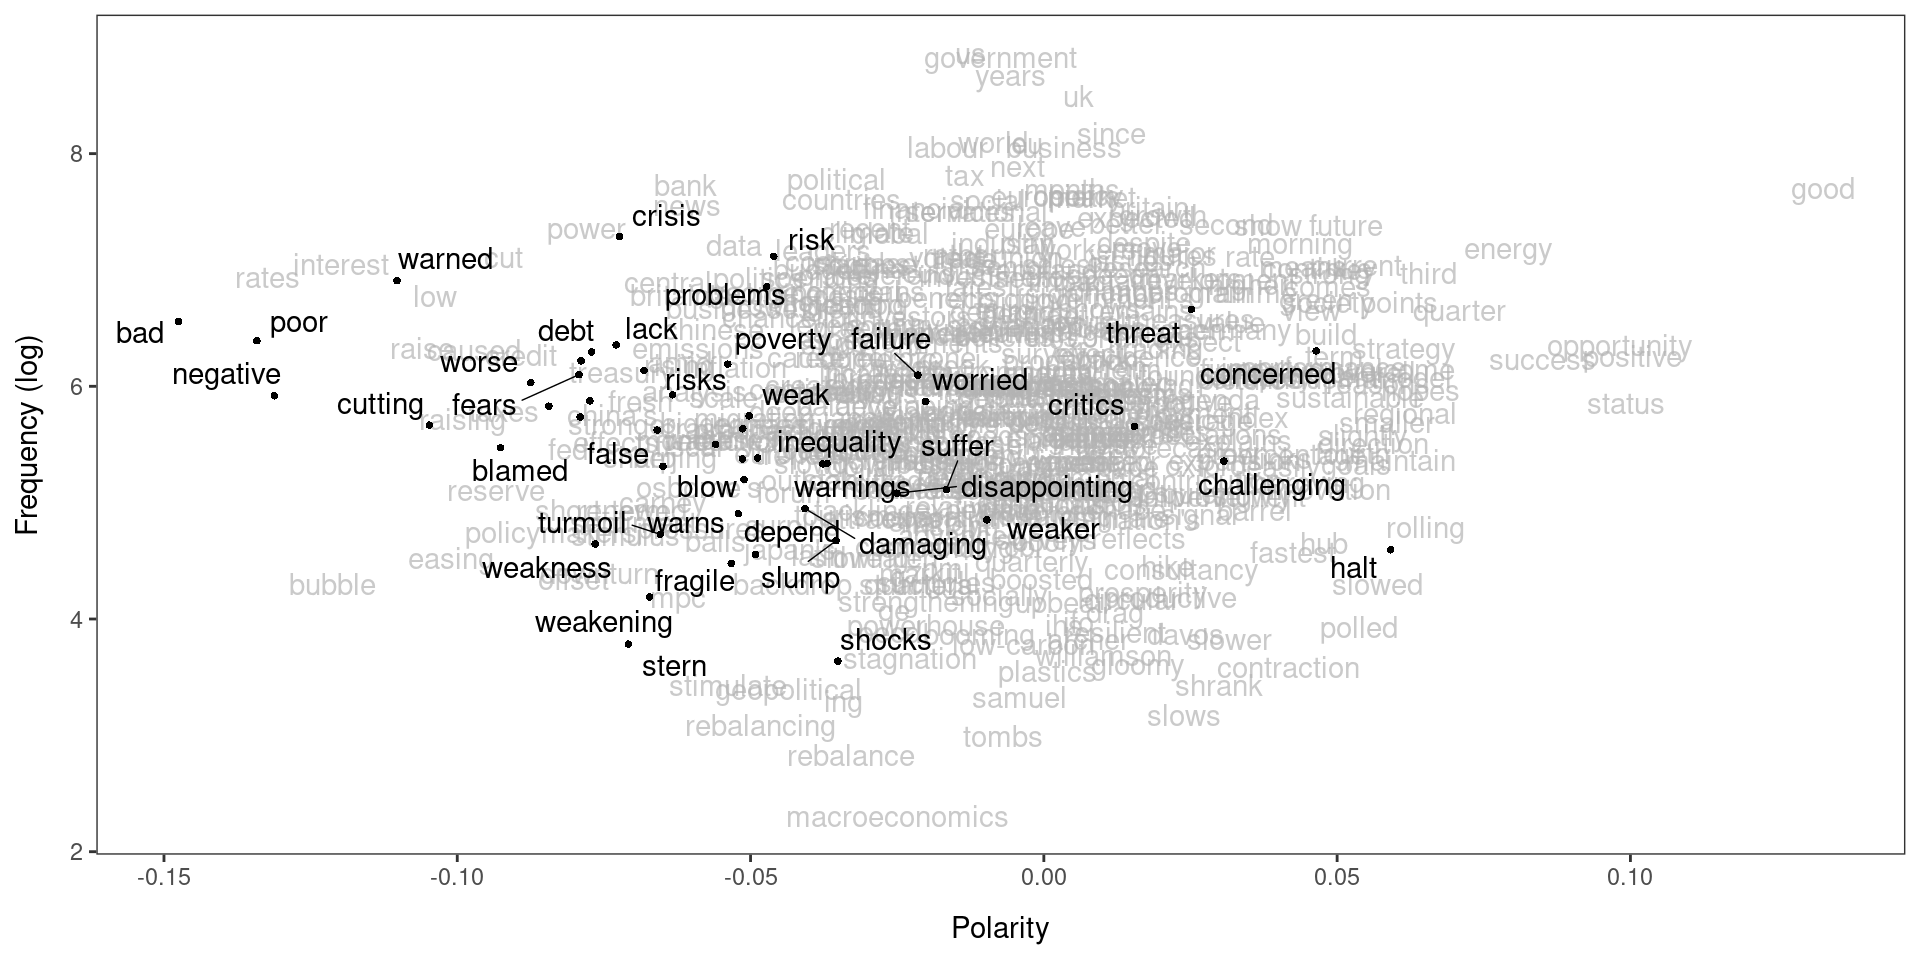
趋势分析
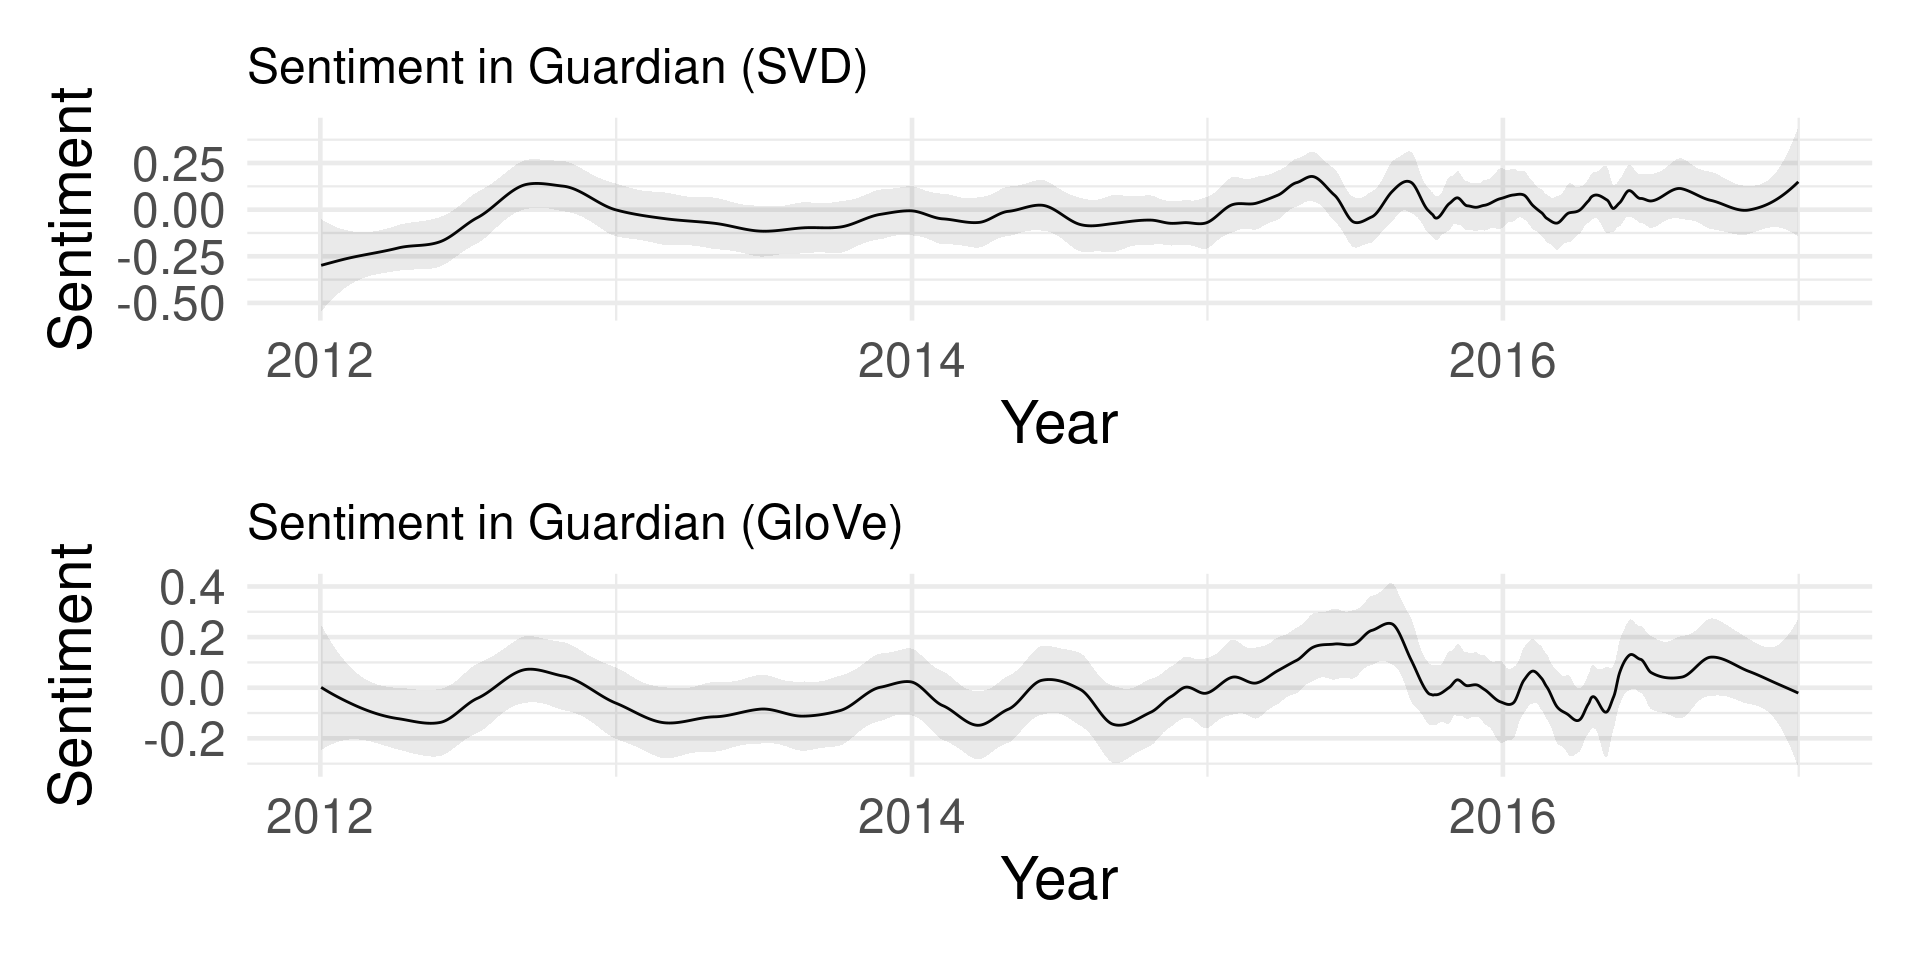
还缺什么

Machine learning is a branch of artificial intelligence (AI) and computer science which focuses on the use of data and algorithms to imitate the way that humans learn, gradually improving its accuracy (IBM 2021).

自监督学习

强化学习

注意力机制 (Attention Mechanism, Vaswani et al. 2017)

一般的word embedding认为所有词和词之间关系都同等重要🤦‍♂️

“Attention is all you need” (Vaswani et al. 2017)

以下是关于大型语言模型中注意力机制的示例翻译:

作为在_____领域的头部企业,我们雇佣了大量高水平的软件工程师。
作为在_____领域的头部企业,我们雇佣了大量高水平的太阳能工程师。

应该在 “_____” 填入什么词?你是如何得出这个结论的?

作为在信息技术领域的头部企业,我们雇佣了大量高水平的软件工程师。
作为在绿色能源领域的头部企业,我们雇佣了大量高水平的太阳能工程师。

自注意力机制

输入一个初始词元嵌入序列,并输出一个新的词元嵌入序列,使初始嵌入能够相互作用

组装起来

  • 由堆叠的注意力机制前馈神经网络层组成的大型神经网络可以使用专用处理器高效并行训练,即 transformer,通常通过预训练(pre-training)获得。
    • → 应用于基于学习成果的生成式(generative)任务
  • 强化学习/微调过程

总结

本讲的核心议题:突破词基限制,找回有用信息

词汇层级的信息汇入

  • Weighing ← 从词频攫取信息
  • N-gram & Collocation ← 从邻居/共现攫取信息
  • Functional words ← 从心理攫取信息

概念层级的信息汇入

  • STM ← 纳入概念关系外部信息
  • SeedLDA ← 纳入背景知识
  • keyATM ← 纳入研究意图

语义层级的信息汇入

  • Word embedding ← 词汇之间的语义关联
  • Self-supervised learning & Attention model ← 自动化和自我提升
  • Reinforcement learning ← 具体任务情境

感谢倾听,欢迎交流

  sammo3182

  yuehu@tsinghua.edu.cn

  https://www.drhuyue.site

参考文献

Bengio, Yoshua, Réjean Ducharme, and Pascal Vincent. 2000. “A neural probabilistic language model.” In Advances in Neural Information Processing Systems. Vol. 13. MIT Press.
Eshima, Shusei, Kosuke Imai, and Tomoya Sasaki. 2023. “Keyword-Assisted Topic Models.” American Journal of Political Science, Early View. https://doi.org/10.1111/ajps.12779.
Gabrielatos, Costas. 2018. “Keyness Analysis: Nature, Metrics and Techniques.” In Corpus Approaches to Discourse, edited by Charlotte Taylor and Anna Marchi, 34–65. Routledge.
IBM. 2021. “What Is Machine Learning (ML)?” Think: Tech news, education; events. September 22, 2021.
King, Gary. 2015. “Big Data Is Not about the Data!” Guest talk presented at the Talk at the capital markets cooperative research centre, Sydney, Australia, November 11.
Liu, Amy H. 2022. “Pronoun Usage as a Measure of Power Personalization: A General Theory with Evidence from the Chinese-Speaking World.” British Journal of Political Science 52 (3, 3): 1258–75. https://doi.org/10.1017/S0007123421000181.
Pennington, Jeffrey, Richard Socher, and Christopher Manning. 2014. “GloVe: Global Vectors for Word Representation.” In Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP), 1532–43. Doha, Qatar: Association for Computational Linguistics. https://doi.org/10.3115/v1/D14-1162.
Roberts, Margaret E., Brandon M. Stewart, Dustin Tingley, and Edoardo M. Airoldi. 2013. “The Structural Topic Model and Applied Social Science.” Advances in Neural Information Processing Systems Workshop on Topic Models: Computation, Application, and Evaluation 1737: 1–4.
Vaswani, Ashish, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. 2017. “Attention Is All You Need.” In Advances in Neural Information Processing Systems. Vol. 30. Curran Associates, Inc.
Watanabe, Kohei. 2021. “Latent Semantic Scaling: A Semisupervised Text Analysis Technique for New Domains and Languages.” Communication Methods and Measures 15 (2): 81–102. https://doi.org/10.1080/19312458.2020.1832976.